
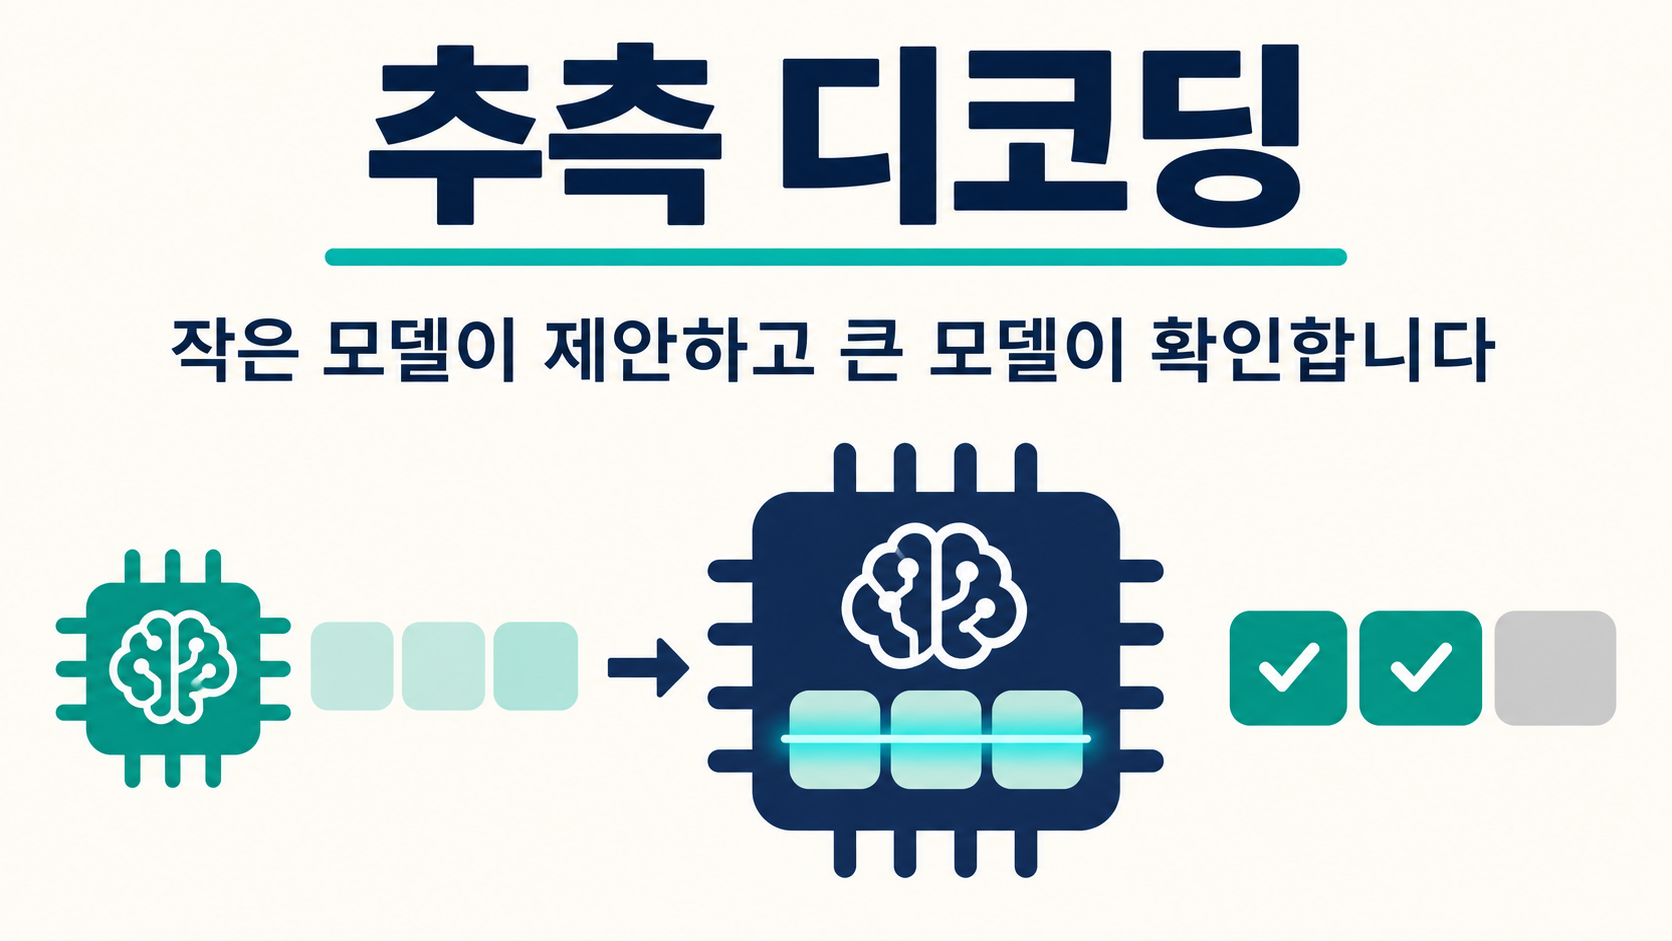
An autoregressive language model normally waits for the large model’s computation before choosing each successive token. Speculative decoding lets a smaller model propose several tokens, then evaluates the relevant next-token probabilities in parallel with the target model. Several tokens can therefore be committed in one iteration. A hypothetical service chatbot and the T5-XXL experiments illustrate how the output distribution is preserved and why actual speedups depend on the setting.
This article examines Fast Inference from Transformers via Speculative Decoding by Yaniv Leviathan, Matan Kalman and Yossi Matias. The work first appeared on arXiv on November 30, 2022; the technical discussion and experimental figures here follow the final ICML 2023 PMLR version.
1. Why an autoregressive response arrives token by token
A service chatbot often reveals its reply gradually. The language model reads the text already committed, computes probabilities for the next fragment and selects one. It then includes that selection in the context for the following prediction.
The fragments are tokens: a token may represent a complete word or part of one. The text preceding the next selection is its prefix. In a chatbot, the user’s input and tokens generated so far provide that context.
Each large-model computation creates another wait. Could a smaller model write the next few fragments in advance, allowing the larger model to examine them together?
2. Drafting first, evaluating the target model in parallel
The smaller model is the draft model; the target model is the larger model originally intended to generate the response. Starting from the current prefix, the draft model generates a short sequence autoregressively.
Suppose a hypothetical chatbot receives draft tokens A, B and C. The target model evaluates next-token probabilities for four inputs in parallel: the current prefix, the prefix plus A, plus A and B, and plus A, B and C. Having the draft makes those inputs available in advance.
Acceptance is decided in order from A onward. If A and B are accepted but C is rejected, A and B are committed and a replacement at C’s position is sampled from a corrected distribution. Computations beyond that point are discarded. If the entire draft is accepted and generation continues, one additional token is sampled from the target model’s next distribution.
Section 2.3 and Algorithm 1 of the paper specify this sequence and its conditions.
3. Acceptance and correction preserve the target distribution
The two models may assign different probabilities to a proposed token. The acceptance probability is the smaller of one and the target-to-draft probability ratio. A proposal is always accepted when its target probability is at least as large as its draft probability; otherwise it is accepted proportionally less often.
Consider an illustrative two-token vocabulary. The draft assigns A 80% and B 20%, while the target assigns A 60% and B 40%. When A is proposed, it is accepted with probability 60/80, or 75%. Across all trials, that contributes 80% × 75% = 60% to A.
Every proposal of B is accepted. The 20% of trials in which A is rejected are corrected to B, the token with remaining target probability in this example. B therefore receives its original 20% plus the corrected 20%, reaching the target’s 40%.
What is preserved is the probability distribution under the same conditioning, not necessarily identical sampled text on repeated runs. Acceptance follows the target model’s generation rule; it does not verify that a chatbot’s statement is factually correct.
Appendix A.1 proves that combining accepted proposals with sampling from the corrected distribution reproduces the target model’s distribution.
4. Reading the T5-XXL timing results in context
The researchers used existing T5 v1.1 checkpoints. The target was T5-XXL with 11 billion parameters; the draft model for the results below was T5-small with 77 million. Tests used a single TPU v4 and batch size one, comparing elapsed time against standard T5X execution of the same target model.
| Task | Draft length | Sampling · temperature 1 | Greedy selection · temperature 0 |
|---|---|---|---|
| WMT English-to-German translation | 7 tokens | 2.6× | 3.4× |
| CNN/Daily Mail summarization | 5 tokens | 2.3× | 3.1× |
A 2.6× translation speedup means that the baseline elapsed time divided by the speculative-decoding time was 2.6. Sampling with temperature one and selecting the highest-probability token at temperature zero produced different ratios. The abstract’s roughly two-to-threefold summary should be read alongside these particular results.
The model sizes and numerical results follow Section 4.1 and Table 2 of the final ICML paper.
5. Why a service may see a different speedup
Accepting a longer initial run of draft tokens reduces serial waits for the target model. Frequent early rejection wastes computations for later draft positions. Time spent producing the draft is also part of each iteration’s cost.
With spare parallel compute capacity, elapsed time can fall even while the total arithmetic workload rises. Draft length and model pairing therefore need separate evaluation. Larger draft models achieved higher acceptance rates in the experiment, but T5-small delivered the greatest measured speedup.
Compare services under matched input lengths and concurrent request counts. Separating time to first token, intervals between later tokens and requests handled per unit time reveals which delay changed. The reported translation and summarization ratios belong to the tested models and hardware.
6. Recording implementation differences for development and patent review
A development record can distinguish draft length, the first rejected position, probabilities used for correction and computation time. Even with the same draft model, implementations may differ in how they choose the lookahead for each request and handle computed results or caches after rejection.
From IPLEX’s patent-review perspective, merely stating that speculative decoding is used does not distinguish a new implementation from the published method. Record the bottleneck, inputs that reveal it, conditions for changing draft length or the verification unit, and measurements affected by the change. These are practical drafting considerations, separate from the paper’s experimental findings.
The original figure labels and forms are preserved; the text explains the source material.
The chatbot and two-token example are illustrative. The timing figures are the paper’s specific T5 experiments, not a general performance guarantee. Preserving a sampling distribution does not certify factual accuracy.
arXiv 2211.17192 · original preprint record
Google Research · the authors’ explanation
FlashAttention-2: making long-context attention run efficiently on GPUs
PagedAttention: how vLLM manages KV cache and GPU memory
Explore IPLEX’s AI practice and consultation materials to explain how your implementation works and where its technical contribution lies.
Explore our AI and patent practice